Gemini Omni
Google's multimodal creation model — where Gemini's reasoning meets the ability to create. Generate and edit video from text, images, video, or audio with natural language. Every edit builds on the one before. Try free with GPT Image 2.5 AI video generator.
Gemini Omni
About Gemini Omni
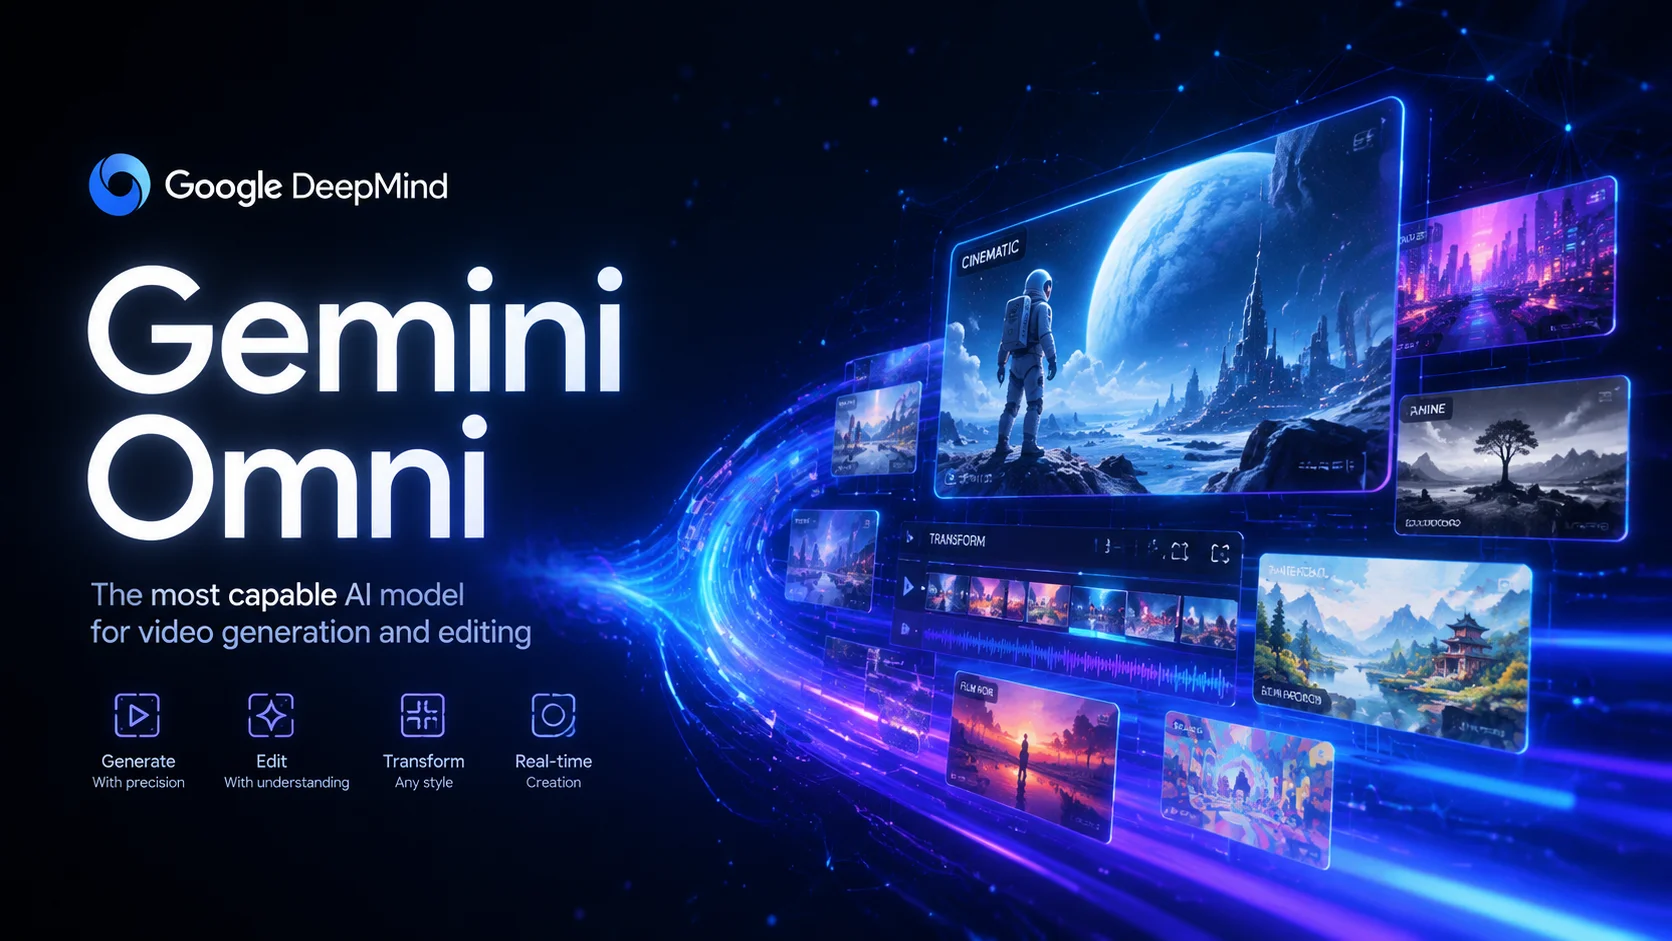
Gemini Omni is Google DeepMind's multimodal creation model, announced at Google I/O 2025. It brings Gemini's reasoning ability together with generative media systems, enabling video generation and editing that goes beyond simple prompt-to-video output. The model understands scenes, actions, environments, physical behavior, and real-world context — producing results that feel intentional rather than random. Gemini Omni Flash is the first model in the Omni family, built for practical video creation and editing workflows where users can transform footage, guide results with references, and refine scenes through natural language conversation.
Key Capabilities
Multimodal input, conversational editing, style transformation, and real-world knowledge — all in one model
Core Features Overview
Multi-Turn Conversational Editing
Gemini Omni introduces a fundamentally different approach to video editing. Instead of starting from scratch with each generation, you can refine your video through a series of natural language instructions. Change the background, adjust the action, replace objects, shift the camera angle, or add visual effects — all while keeping the rest of the video stable. This conversational workflow means you can iterate toward your vision step by step, just like editing a document with tracked changes.
Edit over multiple turns with consistency — change camera angle while maintaining scene coherence across sequential modifications
Multi-turn editing preserves scene coherence across sequential modifications
First establish the scene with a person in a room, then change the lighting to golden hour, then add rain on the window — each edit builds on the last
Sequential environment changes demonstrate conversational refinement
Real-Time Style Transformation
Gemini Omni can transform the visual style of any input video while preserving the underlying motion, structure, and scene composition. Describe the target aesthetic — metallic surfaces, hand-drawn sketches, felt puppets, holographic projections, voxel art — and the model applies the transformation coherently across every frame. The original camera movement, character actions, and spatial relationships remain intact, creating a seamless style transfer that goes far beyond simple filters.
When the person touches the mirror, make the mirror ripple beautifully like liquid, and the person's arm turns into reflective mirror material
Style transformation preserves motion while completely changing visual aesthetics to metallic
When the person touches the mirror, the entire environment turns into 3D voxel art with blocky geometric shapes
Complete environment transformation to voxel art while preserving spatial structure
True Multimodal Input
Unlike models that only accept text or a single image, Gemini Omni can process multiple input types simultaneously. Provide text for direction, images for visual reference, video for motion guidance, and audio for speech or sound synchronization. The model synthesizes all inputs into a single cohesive video output. This makes it practical for real creative workflows where inspiration comes from multiple sources — a storyboard sketch, a reference clip, a voice recording, and a written description can all contribute to the final result.
Add harp sounds synchronized to when I touch each fern leaf. Change the leaf structure to bioluminescent plant life with fireflies flying around
Combining video input with text instructions and audio reference for synchronized output
Visualize protein folding process using real-world scientific knowledge, rendered in claymation style with accurate molecular behavior
Real-world knowledge applied to scientific visualization with creative style
Frequently Asked Questions
Gemini Omni FAQ
What Creators Say About Gemini Omni
"The multi-turn editing is what sets Gemini Omni apart. I can refine a scene step by step instead of regenerating from scratch every time. It actually feels like directing rather than prompting."
Elena Vasquez
Creative Director
"The multi-turn editing is what sets Gemini Omni apart. I can refine a scene step by step instead of regenerating from scratch every time. It actually feels like directing rather than prompting."
Elena Vasquez
Creative Director
Explore More AI Video Models


 +1k