Camera
Play
Dynamic Camera Movement
Tracking, orbiting, whip pans — AI automatically plans camera paths for smooth, cinema-quality footage every time.
Create amazing videos with our free online AI Video Generator. Support Text-to-Video and Image-to-Video using latest AI models like Sora, Kling, Luma, and Runway.
Video Generator
Don't guess — see for yourself. These videos were all generated by AI, showing real performance in camera work, motion, effects, and beat matching.
Fast-paced fights, extreme sports, complex interactions — AI captures motion rhythm and physical details with precision, delivering coherent, realistic, impactful visuals.
Tracking, orbiting, whip pans — AI automatically plans camera paths for smooth, cinema-quality footage every time.
Running, jumping, collisions, environmental interaction — motion logic stays consistent throughout, with no unnatural glitches.
Upload videos to learn camera work, audio for rhythm, images for style. AI understands your references and generates videos that match your vision.
Upload a reference video and AI learns camera blocking and motion logic to generate new footage with the same style.
Whip pans, match cuts, stylized reveals — AI learns transition timing for batch-generating professionally edited segments.
Describe your vision and AI connects scenes, completes action and narrative rhythm. From idea to finished clip in minutes.
Upload music and AI controls cuts and motion to the beat. No more manually syncing TikToks or ads to music.
No editing skills, no expensive gear needed. Just describe what you want or upload your materials and get high-quality videos in minutes. Supports text-to-video, image-to-video, and multimodal references. Used by content creators, brand teams, and independent studios worldwide.
从多款 AI 视频模型中选择,支持文生视频、图生视频、视频转视频等多种生成模式。
Google's latest flagship video generation model. Veo 3.1 Quality features industry-leading physics engine and ultra-high fidelity, perfectly replicating real-world textures, dynamics and details. Supports 16:9, 9:16 and Auto aspect ratios, ideal for commercial-grade high-quality video production.
The standard edition of the Sora series. Maintains OpenAI's superior prompt understanding while optimizing for speed and cost. Perfect for storyboarding, social media shorts, and rapid creative iteration.
HappyHorse is Alibaba's next-generation multimodal video model with native audio-video co-generation. A single unified model handles four scenes — text-to-video, image-to-video, multi-image reference-to-video, and in-place video editing — making it ideal for ads, e-commerce, short drama, and social creatives.
Wan 2.6 is an advanced video generation model supporting text-to-video, image-to-video, and video-to-video modes. Offers duration options of 5s, 10s, and 15s with 720p and 1080p resolutions. Features multi-shot capabilities for creating diverse video content.
Kling Motion Control model precisely controls character movements and poses by uploading reference images and videos. Supports 3-30 second videos, generates character actions consistent with references, ideal for character animation and motion transfer scenarios.
Renowned for capturing complex motion and physical laws. Kling 2.6 excels at generating high-dynamic character movements, intricate object interactions, and cinematic camera movements with fluidity.
ByteDance's advanced video generation model. Seedance 1.5 Pro excels at character animation with precise lip-sync and natural expressions. Features realistic motion physics, supports multiple aspect ratios (1:1, 21:9, 4:3, 3:4, 16:9, 9:16), and offers flexible duration options (4s, 8s, 12s) with optional audio generation.
ByteDance's next-generation video model focused on high visual quality, complex motion, and multi-modal reference control. Seedance 2 supports text, image, video, and audio inputs, making it ideal for professional video production that needs stronger consistency and richer camera language.

Wan 3.0 Video is Alibaba's multimodal video model for text-to-video, image-to-video, reference-to-video, and video editing with image, video, and audio references.

Wan 3.0 Video Prime is the higher-fidelity Wan variant for demanding text, image, and reference-to-video projects with more controlled motion and composition.

ByteDance's latest video model with text-to-video, first/last-frame image-to-video, and multimodal reference-to-video. Supports reference images, videos, audio, 480p/720p, 4–30 seconds, and optional audio generation.
The faster and more cost-efficient version of Seedance 2. It is ideal for rapid iteration, prompt testing, and high-volume content production while still supporting image, video, and audio references.

The lightest Seedance 2 variant for budget-friendly generation. Supports first/last frames and multimodal references at lower per-second cost, ideal for drafts, social clips, and high-volume testing.
Creative video generation model from xAI. Grok Imagine excels at transforming text descriptions into imaginative video content, supports multiple aspect ratios (2:3, 3:2, 1:1, 9:16, 16:9), offers three style modes (fun, normal, spicy), perfect for creative content production and rapid prototyping.
Grok Imagine Video 1.5 Preview is an image-to-video model. It requires one reference image, outputs fixed 720P video, supports 5-15 second durations, and supports 16:9, 9:16, 3:2, 2:3, 1:1, 3:4 and 4:3 aspect ratios.
Grok Video is xAI's advanced video generation model supporting 6s, 10s, 12s, 16s, and 20s durations. Supports text-to-video and image-to-video with up to 5 reference images. Offers multiple aspect ratios (16:9, 9:16, 2:3, 3:2, 1:1) and up to 5000 character prompts for detailed creative control.
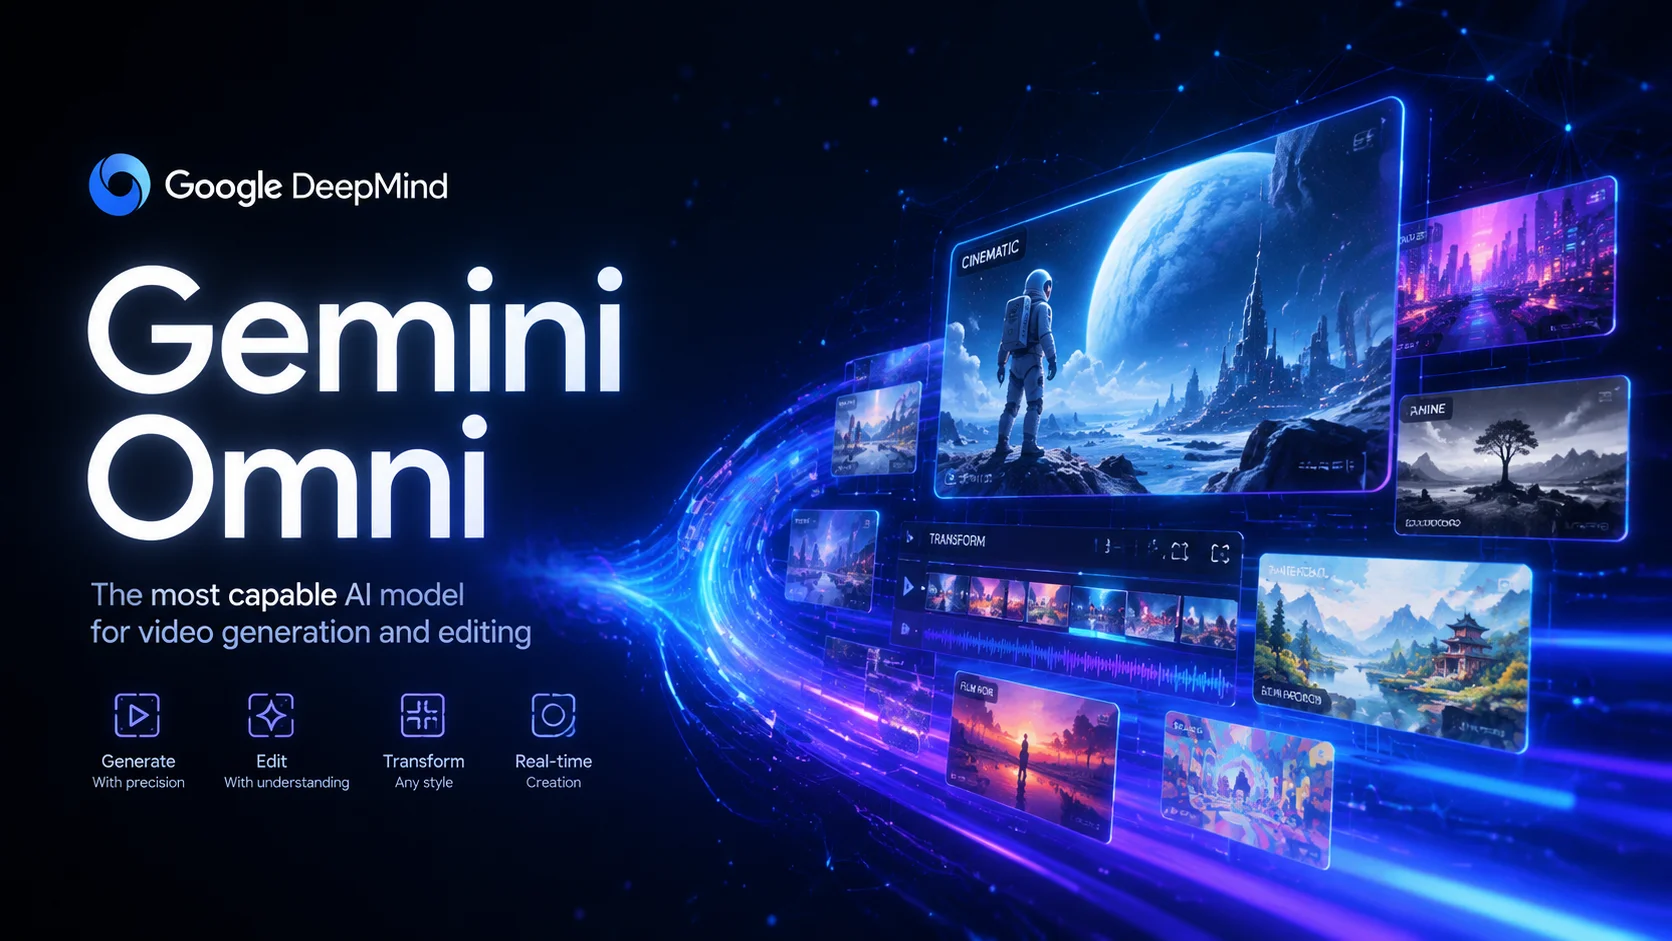
Gemini Omni is Google's advanced video generation model powered by Omni-Flash-Ext. Supports text-to-video, single image-to-video, and 3-image reference fusion. Offers 4/6/8/10 second durations with 16:9 and 9:16 aspect ratios.

Gemini Omni 1.1 Flash is Google's multimodal video model for text-to-video, image-to-video, and reference images with flexible duration and multiple aspect ratios.

MiniMax H3 is a multimodal video model for text, image, and reference-to-video generation with 768p/2K output, flexible duration, and reference audio.
MiniMax H3 Max is a speed-focused video model for text-to-video and first/last-frame image-to-video, with 480p/720p output and 5–15 second clips.

PixVerse V6 is a flexible video model for text-to-video, image animation, first/last-frame transitions, and video extension. It supports 360p to 1080p, 1-15 second clips, and optional native audio.
Turn text, images, or reference materials into high-quality videos. No editing skills needed, no expensive equipment — just great videos in minutes.
Describe what you want or upload an image, and AI generates the video. One platform handles everything from ads to social content.
Tracking shots, orbiting, smooth transitions — AI handles the camera work automatically. You describe, it delivers professional quality.
Automatically connect scenes with narrative flow and rhythm. Brand stories, product demos, and creative storyboards — all in one go.
Upload a track and AI syncs cuts to the rhythm. Perfect for TikTok viral content, ad spots, and music videos without manual timing.
Open your browser and create anywhere — phone, tablet, or desktop. High-output production even during your commute.
Images set style, videos set camera work, audio sets rhythm. What you reference is exactly what you get.
Still have questions? Email our team
 10,000+